Explainer
LLMO: shaping how large language models describe your brand
LLMO, short for large language model optimization, is the work of making sure ChatGPT, Gemini, Claude, Copilot and Perplexity describe your brand accurately and recommend it where it fits, whether or not they run a web search for the answer. This post is for marketing leads and founders who have asked an assistant about their company and disliked the reply; it explains where models get their information, what you can control, and how to correct mistakes.
Get a free AEO visibility check
Two lines is enough. A specialist replies within one business day.
Quick answer
What is LLMO?
LLMO (large language model optimization) is improving how AI assistants such as ChatGPT, Gemini and Claude describe and recommend your brand. It covers two routes: the training data models learn from, controlled partly through crawler tokens like GPTBot and Google-Extended, and the live search results they cite, which depend on crawlable pages and third-party mentions.
- LLMO covers both what models learned in training and what they retrieve live.
- Training crawlers and search crawlers use different tokens and need separate decisions.
- Third-party sources such as Wikipedia, Reddit and YouTube shape model answers heavily.
- Wrong answers are fixed mostly by fixing the sources engines read.
What is LLMO?
LLMO is large language model optimization: improving the accuracy and favorability of what AI assistants say about your brand. It overlaps with AEO and GEO but puts more weight on answers that come from a model's own knowledge rather than a live search.
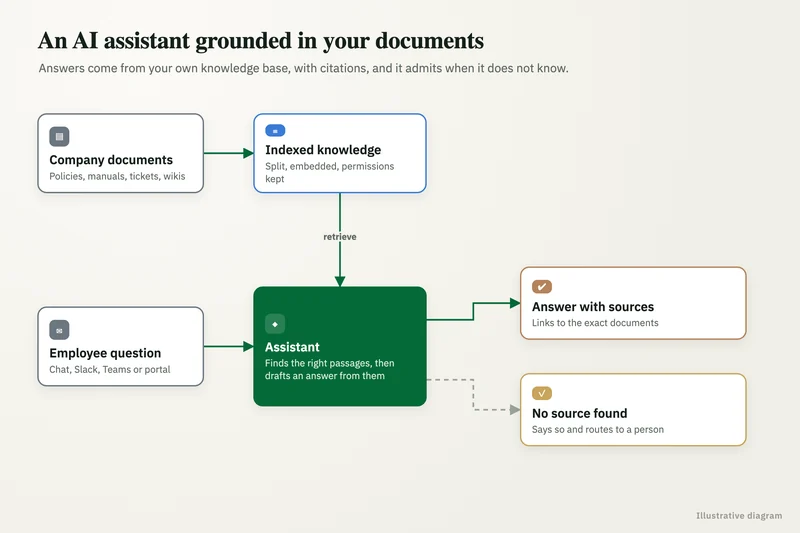
When you ask ChatGPT or Claude about a company, the reply can come from two places. Either the model answers from what it absorbed in training, or it runs a web search and summarizes the pages it finds, usually with citations. Most questions now trigger some search, but the model's prior view still frames how it reads those results.
That is why LLMO is about representation as much as rankings. The aim is that any assistant, asked about your category, names you correctly, describes what you do in your terms, and gets the facts right: pricing model, locations, integrations, leadership.
How do large language models learn about a brand?
Through training data collected by crawlers and data partnerships, and through live retrieval at answer time. Each route has its own controls and its own fixes.
The table separates them. Training shapes the model's background knowledge and changes slowly, when new models are trained. Retrieval shapes individual answers and can change within days of a page update.
| Training route | Retrieval route | |
|---|---|---|
| What it shapes | The model's background knowledge of you | The specific answer and its citations |
| Crawler tokens | GPTBot, ClaudeBot, Google-Extended, Applebot-Extended, CCBot | OAI-SearchBot, Claude-SearchBot, PerplexityBot, Googlebot, Bingbot |
| How fast changes show | Only when a new model is trained | OpenAI says OAI-SearchBot robots.txt changes take about 24 hours |
| Main levers | Accurate, widely repeated facts on trusted sites | Crawlable pages, clear answers, current third-party coverage |
| Can you opt out? | Yes, via robots.txt or Cloudflare managed robots.txt | Yes, but you then disappear from that engine's answers |
Should you block AI training crawlers?
It depends on whether you want models to learn about you directly from your site. Blocking training crawlers protects content but leaves the model's view of you to other sources.
Google-Extended, for example, is a robots.txt control token that governs Gemini training and Gemini Apps grounding, and Google says it does not affect inclusion in Google Search. GPTBot only collects OpenAI training data, and blocking it opts out of training only. Cloudflare's managed robots.txt can disallow GPTBot, ClaudeBot, Google-Extended, Applebot-Extended and CCBot in one setting.
For a publisher whose content is the product, blocking training is often sensible. For a brand that wants assistants to describe it accurately, allowing training crawlers on factual pages such as About, product and pricing can make sense, while keeping the search crawlers open either way. Decide page type by page type, not site-wide by reflex.
Which sources shape what LLMs say about you?
Widely cited reference and community sites carry the most weight: Wikipedia, Reddit, YouTube, LinkedIn, review platforms and the major press. Your own site matters, but it is one voice among many.
A secondary analysis by presenc.ai puts Wikipedia at roughly 7.8% to 13% of ChatGPT citations. Ahrefs found YouTube mentions correlate about 0.737 with AI visibility, the strongest correlate it measured, ahead of backlinks. Reddit has data agreements with both Google and OpenAI, so community discussion feeds directly into the systems answering your buyers.
Sources also shift quickly. Semrush found ChatGPT cited Reddit in about 60% of responses before that fell to about 10% within weeks in 2025. Good representation work therefore spreads accurate information across several trusted sources rather than betting on one.
Does it work differently for new and established brands?
New brands can move their AI visibility with their own content; established brands mostly cannot. For them, what third parties say carries the result.
An Ahrefs experiment published in July 2026 found self-promotional pages produced 82% of a new brand's new AI mentions but only 6% for an established brand, where third-party content did most of the work. Being cited is also not the same as being recommended: the same experiment found answers that cited a promotional page often still did not recommend the brand. If you are new, publish clear category, comparison and pricing pages early. If you are established, invest in reviews, press and community presence.
Which pages help models describe your brand accurately?
Plain factual pages that state who you are, what you sell, for whom, where and at what price help models most, because they give both crawlers and retrieval systems an unambiguous source to quote. Marketing copy full of adjectives gives a model little it can safely repeat.
Write each fact once, clearly, and repeat it consistently everywhere your brand appears: the same company description, founding details, locations and product names on your site, in Organization schema, on LinkedIn, on review platforms and in directory listings. Where these disagree, models tend to blend them, which is how outdated pricing or a former product name keeps resurfacing in answers.
- An About page with a one-paragraph company description and key facts.
- Product or service pages that name the category and the buyer in the first sentence.
- A pricing or pricing-model page, even if exact prices are quoted on request.
- Comparison and alternatives pages that are fair to competitors.
- A dated changelog or news page for launches, renames and discontinued products.
How do you fix wrong information an LLM states about your brand?
Mostly by fixing the sources the engines read, because direct correction routes are limited. Start with a log of the wrong claims and where each one appears to come from.
Google offers routes for its own surfaces: you can claim your Knowledge Panel through a linked official profile, with verified owners' suggested changes getting priority, and use "Report a problem" on an AI Overview. OpenAI offers corrections only for personal data, through its privacy portal, and says it will not be able to correct inaccuracies in every case. No brand correction channel at OpenAI or Copilot was found.
So the practical fix is upstream: correct your own pages and schema, update outdated directory and review profiles, ask publishers to correct errors, and make the accurate version the one most sources repeat. Then re-run the same prompts monthly to see whether answers change.
- List each wrong claim, the engine and the prompt that triggers it.
- Check which cited sources carry the error and correct or contact them.
- Update Organization schema, sameAs links and official profiles to match.
- Use Knowledge Panel and AI Overview feedback routes for Google surfaces.
- Re-run the prompts monthly and record whether the claim persists.
How do you measure the way models describe you?
Run a fixed set of prompts about your brand and category in each assistant, monthly, and score accuracy, recommendation and citations. Unlike search, there is no single report that covers it.
Include brand prompts ("what does [brand] do"), category prompts ("best [category] for [use case]") and comparison prompts. Record whether the answer is accurate, whether you are recommended, which competitors appear and which URLs are cited. Bing Webmaster Tools AI Performance adds first-party Copilot citation data, and GA4 shows referrals from chatgpt.com, perplexity.ai, copilot.microsoft.com and gemini.google.com.
How does LLMO relate to AEO, GEO and LLM SEO?
They share one toolkit. AEO stresses being the direct answer, GEO stresses citations in generated responses, and LLMO stresses how the model represents you, including in answers that involve no search at all.
At AEO Services Agency, the AEO and GEO practice of Greenwolf Tech Labs, our LLM SEO service covers this representation work. Engagements start with a free AEO visibility check, run at a fixed price, and measure a fixed prompt set before and after changes. No one can promise how a model will describe you; the work is to make the accurate version the easiest one to find.
FAQ
Frequently asked questions
What does LLMO stand for?
LLMO stands for large language model optimization. It means improving how AI assistants such as ChatGPT, Gemini, Claude and Copilot describe and recommend a brand, both from training data and from live web searches they run when answering.
Is LLMO the same as GEO?
They overlap heavily. GEO focuses on being cited in AI-generated answers that draw on search, while LLMO also covers what models say from their training data without searching. The tactics, from crawler access to third-party mentions, are largely shared.
Can I make ChatGPT say something specific about my company?
Not directly. OpenAI offers no brand correction channel and only handles personal-data corrections. You can influence answers by making accurate facts consistent on your site, in schema and across trusted third-party sources the model reads.
Does blocking GPTBot hurt my visibility in ChatGPT?
Not in ChatGPT search. GPTBot only collects training data, while OAI-SearchBot decides whether your site can appear in ChatGPT's search answers. Blocking GPTBot does mean future models learn about you only from other sources.
How long does LLMO take?
Answers that rely on live search can change within days of a fix, since OpenAI says robots.txt changes for its search crawler take about 24 hours. A model's background knowledge changes only when a new model is trained, which can take much longer.
Why does ChatGPT describe my company with old information?
Usually because outdated facts still appear on sources it reads, such as old directory listings, press articles or review profiles, or because the answer came from training data gathered before your change. Update those sources, publish a dated page stating the current facts, and re-check the answer monthly.
Keep reading
Related pages
Get started
Find out what AI says about you
Send your website and three questions your buyers ask. Within one business day we reply with how ChatGPT, Google AI Overviews and Perplexity answer them today, who they cite instead of you, and a fixed-price plan.
- Free AEO visibility check
- Fixed quote before any work starts
- Measured on citations and AI referrals, not promises
Prefer email? info@aeoservicesagency.com
Get a free AEO visibility check
Two lines is enough to start.